Start a conversation

WF384

Private inference at enterprise scale

High-capacity private AI for larger organisations.

A dedicated rack platform for multiple departments, multiple models, demanding retrieval-augmented generation (RAG) and agent workloads.

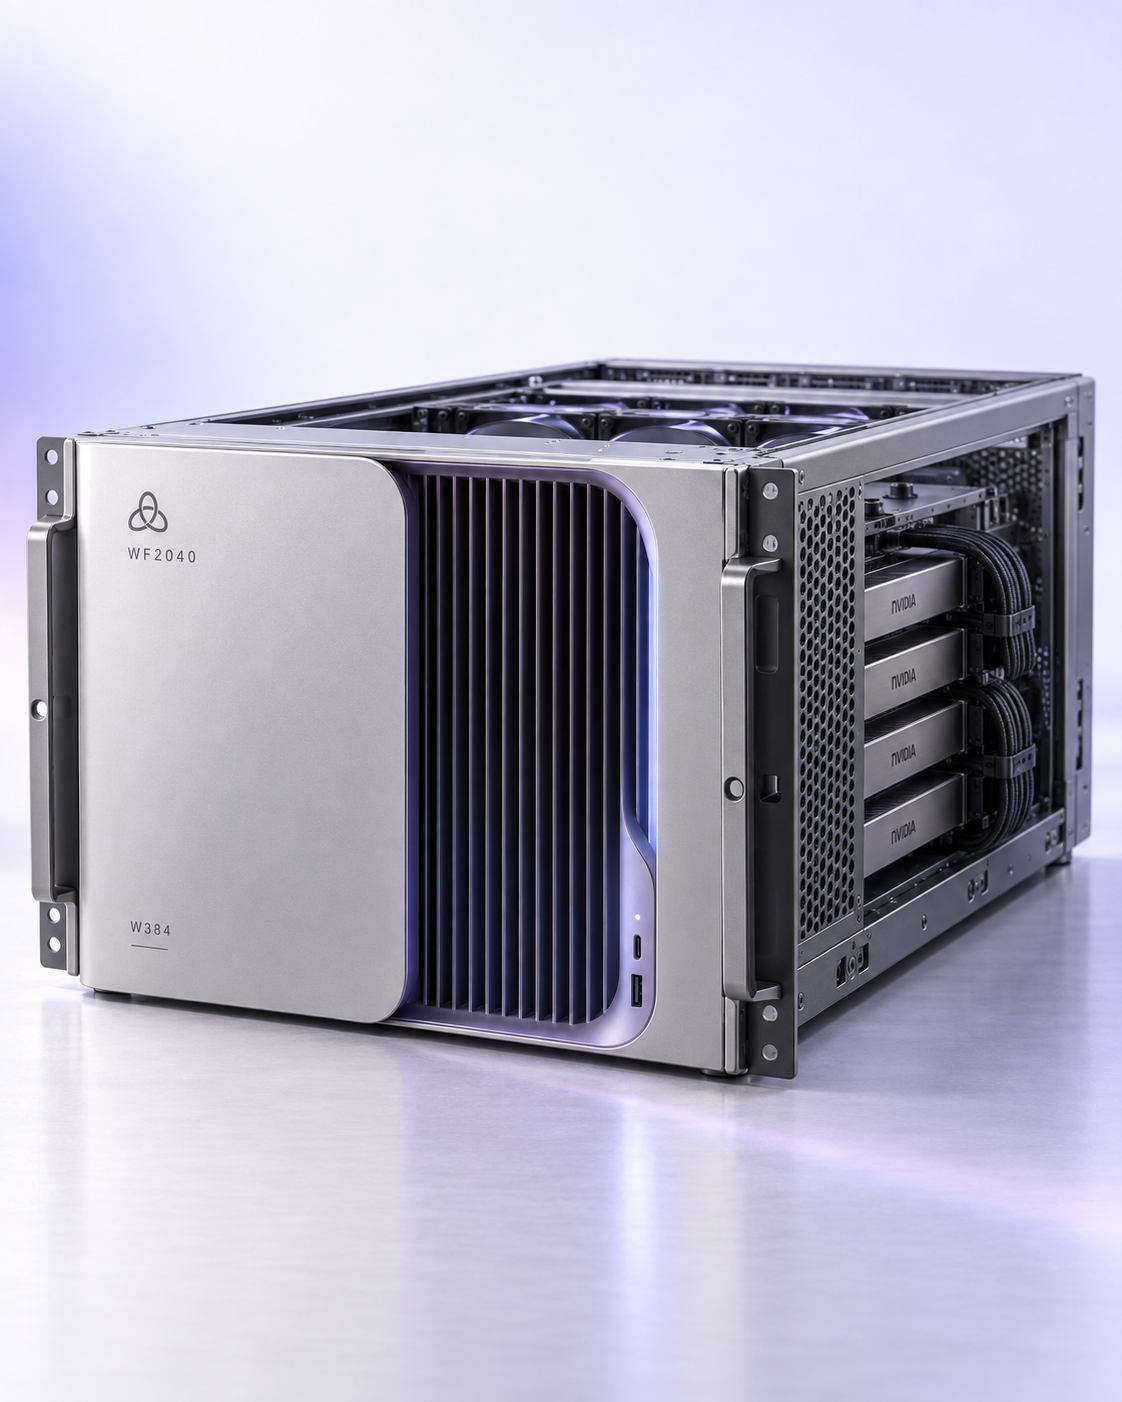
WF2040 WF384 rack server in pearl silver, with four graphics cards and blue and lavender accents

Recommended configuration.

Sized for your workloads, deployment environment and integration requirements.

Compute & memory

GPUs
4 × NVIDIA RTX PRO 6000 Blackwell Server Edition
Total GPU memory
384 GB GDDR7 ECC, aggregate across four GPUs
Aggregate GPU memory bandwidth
Approximately 6.39 TB/s
Peak FP4 Tensor performance
Approximately 16 PFLOPS aggregate
CPU
High-core-count AMD EPYC platform, with single- or dual-socket configurations
System RAM
1 TB ECC DDR5 standard, configurable to 2 TB+

Storage & infrastructure

Boot storage
2 × enterprise NVMe SSD in RAID 1
AI / data storage
30–60 TB usable enterprise NVMe, configurable upward
Networking
2 × 100 GbE recommended; 25 GbE minimum
Management
Dedicated BMC / IPMI / Redfish management interface
Power
Redundant high-efficiency PSUs, sized for approximately 2.4 kW of GPU load plus system overhead
Chassis
4U / 5U rack server with front-to-back cooling
Deployment
On-premises, colocation or private datacentre

Software, integration & control

Operating system
Ubuntu LTS / supported enterprise Linux
Inference
vLLM / TensorRT-LLM / Triton, as appropriate
API
OpenAI-compatible internal API endpoint
Identity
Entra ID / Active Directory / OIDC / SAML integration
Storage integrations
SharePoint, file shares, object stores and SQL / data platforms
Observability
GPU telemetry, request logging, model metrics, utilisation, latency and audit trail
Isolation
NVIDIA MIG where appropriate, containers and departmental access policies

GPU figures aggregate four cards, each rated at 96 GB, 1,597 GB/s and 4 PFLOPS FP4. These totals describe hardware capacity and theoretical peak performance; application throughput depends on the model, software and workload. NVIDIA GPU specifications.
Build the environment
around your work.

Compare the systems

Models

Deploy AI models selected for the work they need to perform.

Knowledge

Connect approved organisational information to your private AI environment.

Agents

Give AI controlled access to tools, systems and defined business processes.

Management

Monitor, maintain and evolve the platform as models and requirements change.

Build capability you control.

Private models. Private knowledge. Dedicated infrastructure.

Start a conversation